Review the user-agent details
Review rules before placing the file at the site root. Compare the reported user-agent, allow, disallow with the page or domain you intended to check.
Check a website’s current robots.txt and generate a starter file with a sitemap reference. Review crawl rules before publishing it at your site root.
Use Robots.txt Generator ↗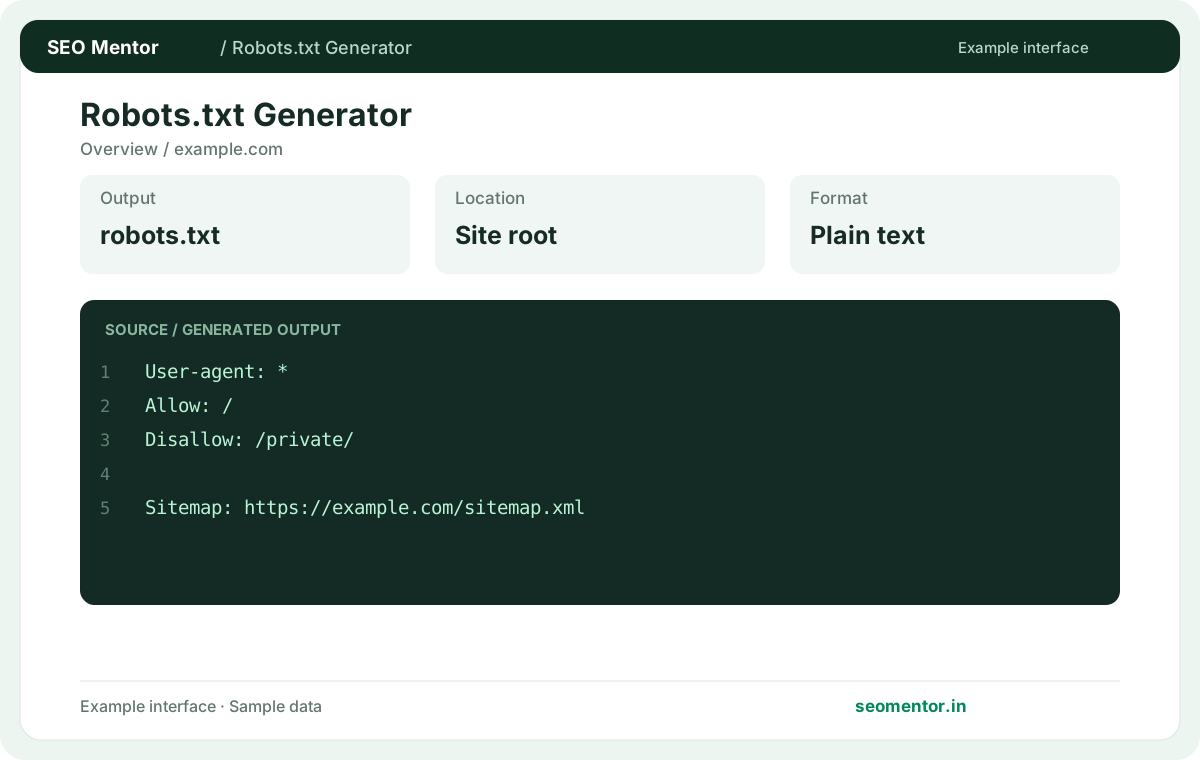
Enter the required details to explore the available output and report options.
Robots.txt controls compliant crawling, not guaranteed deindexing; test the final rules on the live domain. Check the inputs and output carefully before implementation.
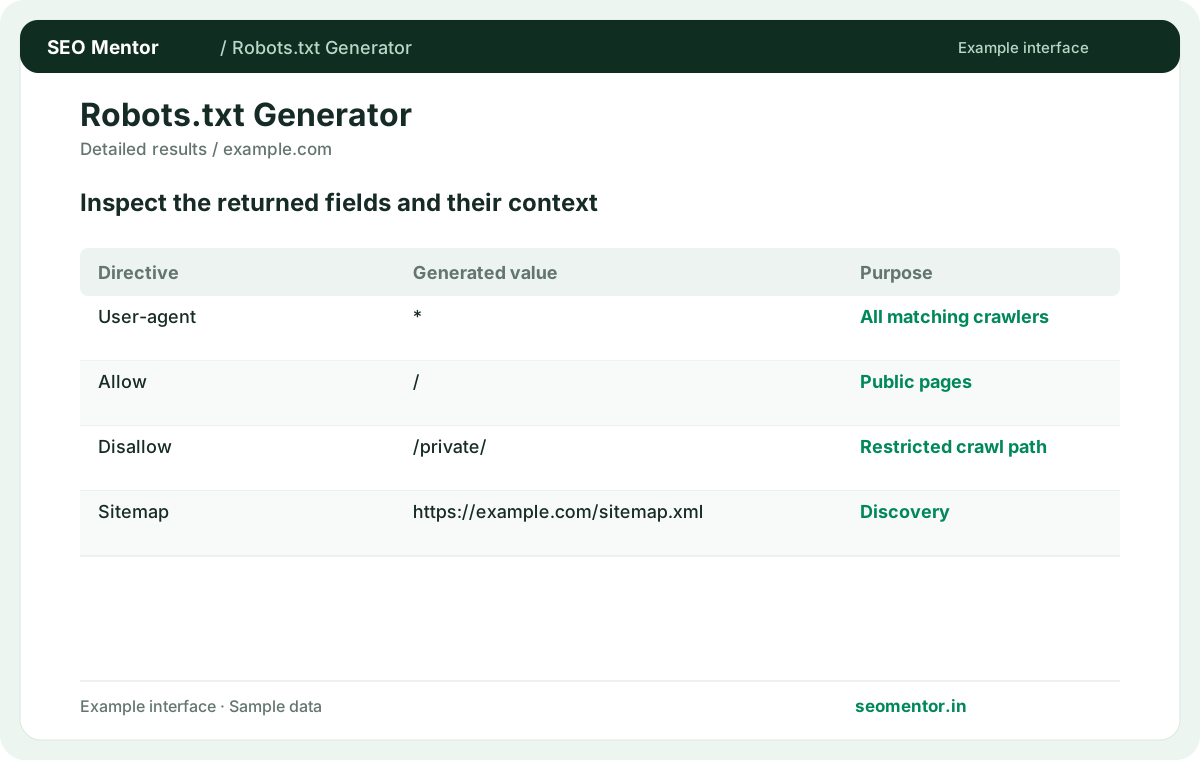
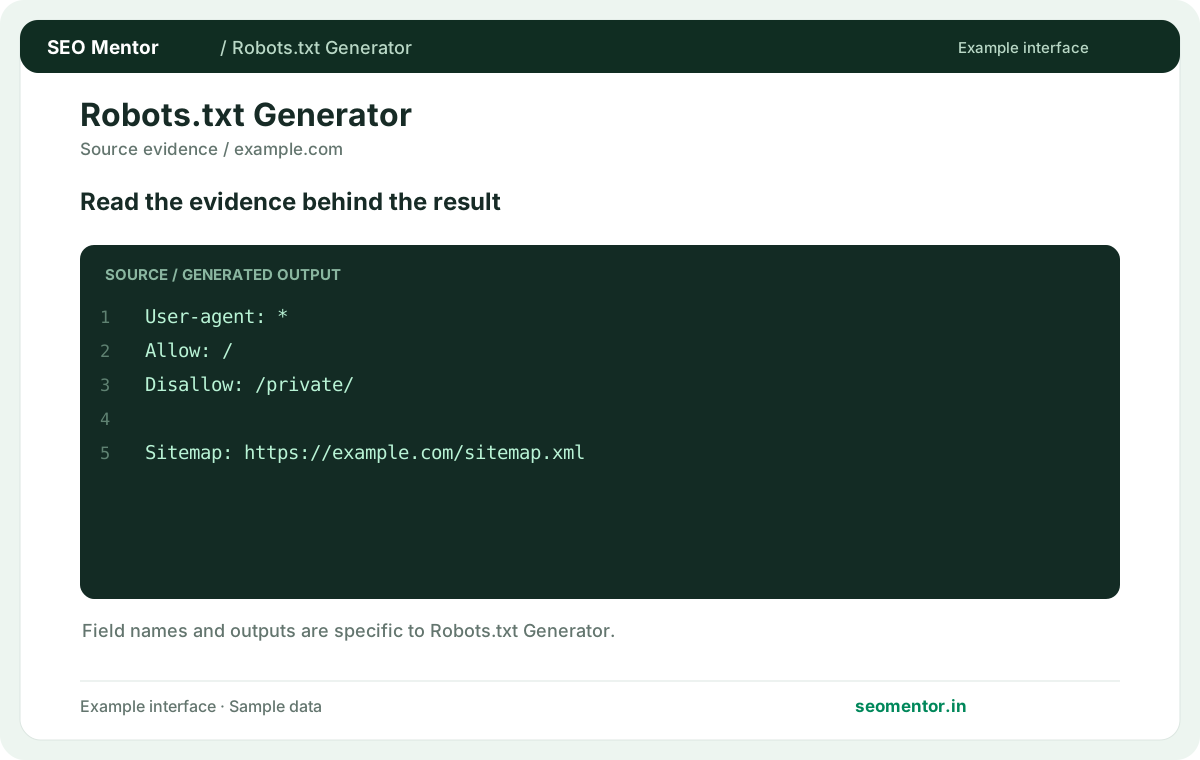
Consider user-agent rules, allowed page paths, disallowed folders together, rather than relying on one visual indicator.
Robots.txt controls compliant crawling, not guaranteed deindexing; test the final rules on the live domain. Compare the draft with the real website and correct placeholder values.
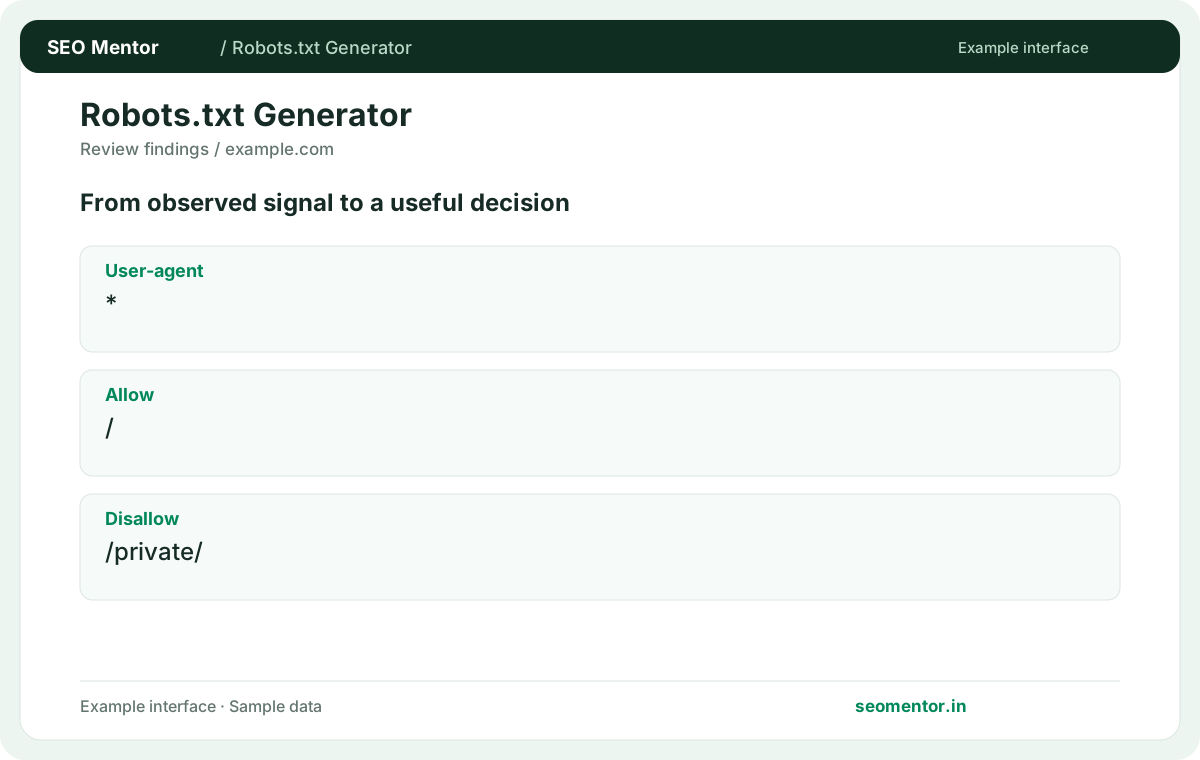
Use the output as a starting point, check it on the live website and revisit it when the underlying content changes. Robots.txt controls compliant crawling, not guaranteed deindexing; test the final rules on the live domain.
Prepare crawler rules for the public and restricted paths on your website. Keep important service and product pages accessible where intended, and review each directive before publishing the file.
Review rules before placing the file at the site root. Compare the reported user-agent, allow, disallow with the page or domain you intended to check.
Do not use robots.txt as access control for private data. Test critical paths after publishing.
Keep the result alongside the page or domain reviewed, so you can compare the evidence after making changes.
It provides a basic crawl configuration and a sitemap reference for the tested site. Review both before uploading.
Related check — How do I add the sitemap address? Use the full public sitemap URL. Test that it responds successfully before referencing it.
Add deliberate directives where they fit your public crawl policy. Protect sensitive pages with real access controls.
Related check — How do I avoid blocking important assets? Check paths for CSS and JavaScript used by public pages. Review whether crawlers need those resources to interpret the page.
Publish it at the root of the relevant hostname and protocol. Confirm the public URL returns the file.
Related check — What should I check after deployment? Fetch the live robots file and test representative URLs. Review caches if the old file remains visible.
Use the full public sitemap URL. Test that it responds successfully before referencing it.
Related check — What does the starter file contain? It provides a basic crawl configuration and a sitemap reference for the tested site. Review both before uploading.
Compare current rules with the draft. Preserve necessary crawler restrictions and allowances you still intend.
Before replacing a live file, keep a copy and compare the generated sitemap entry, existing named crawler groups and intentional exclusions. Test a public article, a restricted path and an important asset after deployment.
It defines fallback instructions for crawlers without an applicable named group. Check any more specific groups separately.
Related check — Can I include comments in the file? Comments can document why rules exist. Keep instructions clear for the next person reviewing the crawl policy.
Small path changes can affect a large section. Test one intended blocked path and one intended allowed page.
Related check — Should I block admin paths by default? Add deliberate directives where they fit your public crawl policy. Protect sensitive pages with real access controls.
Check paths for CSS and JavaScript used by public pages. Review whether crawlers need those resources to interpret the page.
Related check — Why should I test a path after editing? Small path changes can affect a large section. Test one intended blocked path and one intended allowed page.
Comments can document why rules exist. Keep instructions clear for the next person reviewing the crawl policy.
Related check — Can I safely replace an existing file wholesale? Before replacing a live file, keep a copy and compare the generated sitemap entry, existing named crawler groups and intentional exclusions. Test a public article, a restricted path and an important asset after deployment.
Fetch the live robots file and test representative URLs. Review caches if the old file remains visible.
Related check — Where is the generated file installed? Publish it at the root of the relevant hostname and protocol. Confirm the public URL returns the file.
SEO Mentor helps you identify opportunities. SEOKart can help put those findings into action with professional SEO services, technical improvements and ongoing optimisation.
Explore SEOKart SEO Services